Most teams send every AI task to the same place: a frontier LLM. That includes the small, repetitive calls, like tagging a support ticket, scoring a lead, or deciding whether an agent should retry a step.
At ten items, nobody notices. At 100,000, those calls turn into long runs, big bills, and free-text answers your code still has to parse and validate.
Jev AI was built for exactly those decisions. This guide explains how Jev differs from an LLM, where each one performs best, and how to put both to work inside PromptQL.
Key Takeaways
- Jev is TypeSafe AI's "System One" model. It returns typed decisions with confidence scores, while an LLM generates text.
- Jev is far faster and cheaper for repeated, closed questions. LLMs are stronger at reasoning, writing, and open-ended work.
- The most efficient AI setups use both: Jev for high-volume decisions and an LLM for the steps that need language.
Two Models Built for Two Different Jobs
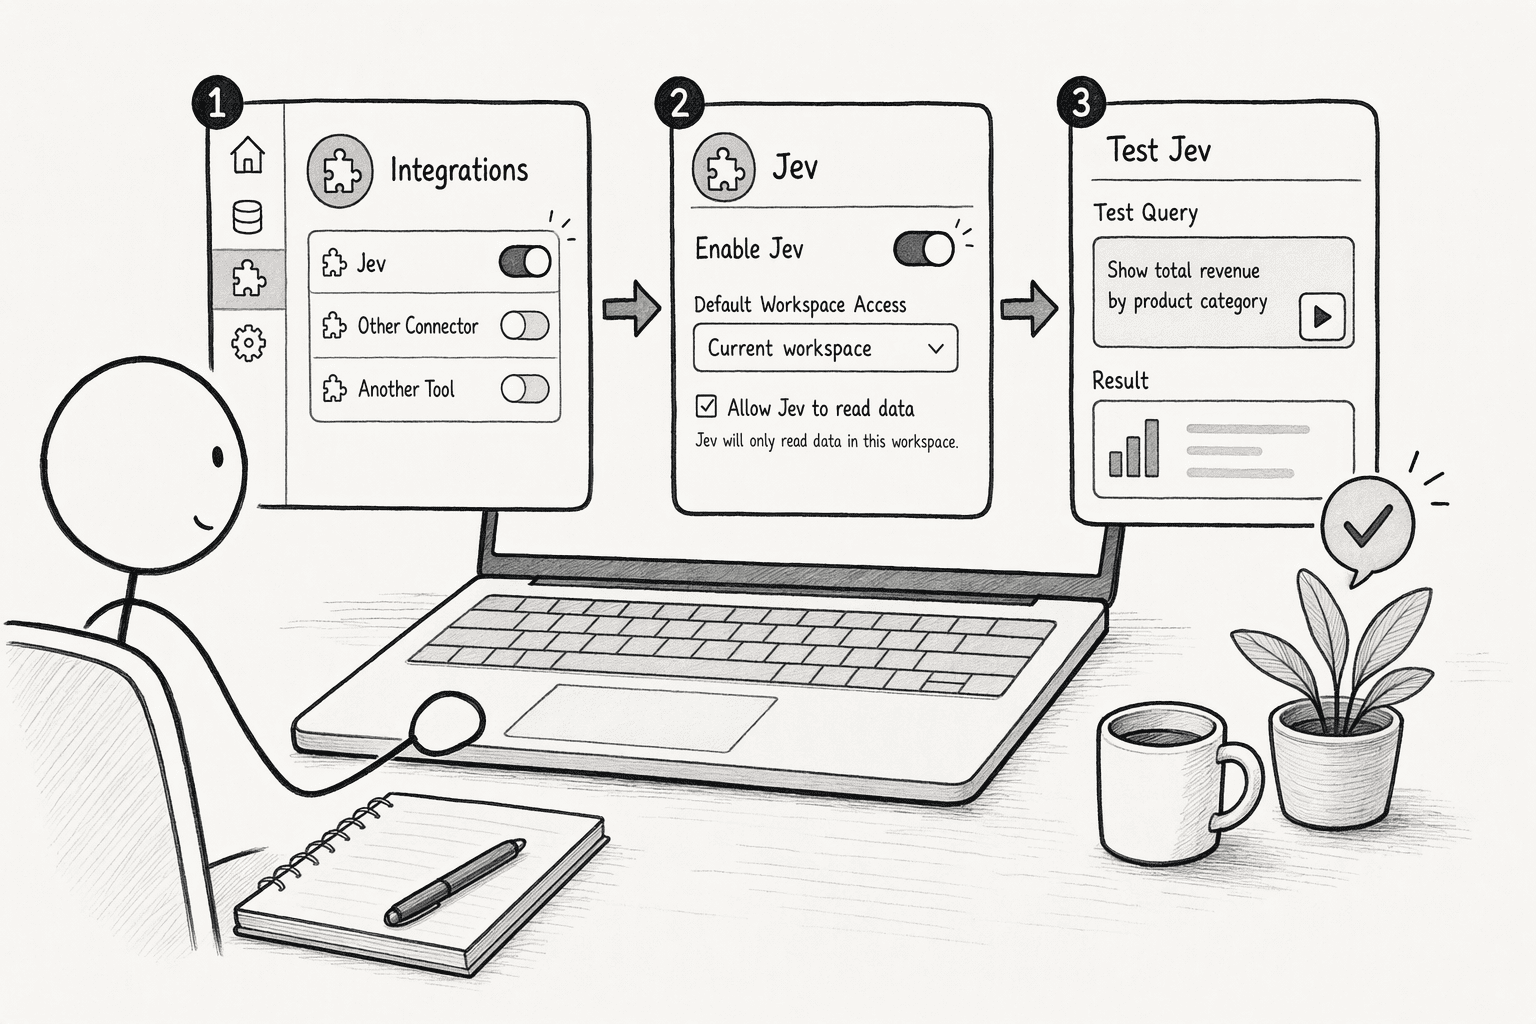
AI models are not interchangeable. Some are designed to think out loud, explain themselves, and write. Others are designed to make one narrow call in a fraction of a second.
Jev and LLMs sit on two opposite ends of that spectrum. Once you know what each one is, the differences between them become easy to follow.
What Is Jev?
Jev is an AI decision model from TypeSafe AI. You give it a state (text or JSON) and a set of closed questions, and it returns typed answers: a choice from a list, a score on a scale, or a yes/no probability. Every answer comes with a confidence score, and Jev never generates free text.
TypeSafe calls Jev its first "System One" model, a nod to the fast, intuitive thinking described in Daniel Kahneman's Thinking, Fast and Slow. It launched on September 15, 2026, and is built for software to call directly rather than for people to chat with.
What Is an LLM?
A large language model (LLM) is an AI model trained on huge amounts of text to understand and generate human language. It produces its answers one token at a time, which lets it write, summarize, answer questions, reason through problems, and write code.
Familiar examples include the models behind ChatGPT, Claude, and Gemini.
Jev vs LLMs at a Glance
This table sums up how the two models compare on the factors that matter most when you're choosing between them:
| Factor | Jev | LLM |
|---|
| Output | Typed values only (choice, score, or yes/no probability) | Free-form text, optionally shaped into JSON |
| How answers are produced | All questions answered in one parallel pass | One token at a time, in sequence |
| Speed per call | 70 to 500 milliseconds | Several seconds to minutes for frontier models |
| Pricing | $0.042 per million input tokens, free output | Roughly $0.20 to $10 per million input tokens, with output costing more |
| Confidence signal | Built into every answer | Self-reported and often unreliable |
| Explains its answer | No | Yes |
| Best-fit tasks | Classification, scoring, routing, verification | Writing, reasoning, planning, open-ended questions |
| Setup | Define questions and allowed answers | Write a prompt |
Key Differences Between Jev and LLMs
The table gives you the overview. The sections below explain what those differences mean in practice, including what the headline claims around Jev actually measure.
1. Output and Predictability
Jev can only return answers you define in advance. If you give it four categories, you'll always get one of those four, so there's nothing to parse and no chance of a malformed response.
An LLM writes its answer out, even when you ask for JSON. That means your code still needs to check the format and handle anything unexpected.
TypeSafe describes Jev as a model that "can't hallucinate." That's true for the format of the output. Jev can still choose the wrong option, and it can do so with high confidence, so you should always test it on your own data.
2. Speed at Scale
Jev answers every question in a request at once, in a single parallel pass. Adding more questions to the same call barely changes the response time.
LLMs generate each token based on the ones before it, which gets slow at volume. In a MotherDuck benchmark on 100,000 news articles, Jev finished in 40 seconds at 89% accuracy. A comparable LLM took nearly 32 minutes and reached 88%.
You'll often see Jev described as "193.6x faster" than LLMs. That figure compares Jev with the slowest model in TypeSafe's tests. Against GPT-5.6 Terra, the model TypeSafe itself calls the closest match in intelligence, Jev is roughly 25x faster, which is still a large gap.
3. Cost Structure
Jev charges only for input, at $0.042 per million tokens, and output is free. LLMs bill for both input and output, and output tokens usually cost several times more than input.
The difference adds up quickly. In the same MotherDuck test, classifying 100,000 rows cost $0.50 with Jev and $37.58 with the comparable LLM.
The widely shared "444.6x cheaper" figure compares Jev with the most expensive model TypeSafe tested. Against GPT-5.6 Terra, the gap is closer to 76x.
4. Confidence Scores
Every Jev answer includes a probability distribution and a confidence score. That gives you a clear signal to act on: automate the answers Jev is sure about and send the uncertain ones to a person.
The confidence score reflects how clearly one answer beat the others. It isn't a guarantee that the answer is right, and independent tests of TypeSafe's calibration claims haven't been published yet.
TypeSafe's documentation suggests starting with automatic action above 0.9 and human review below 0.5, then adjusting based on your results. The confidence score reflects how clearly one answer beat the others. It isn't a guarantee that the answer is right, and independent tests of TypeSafe's calibration claims haven't been published yet.
LLMs can give you a confidence number if you ask for one. However, that number is generated like any other text, and models tend to be overconfident.
5. Accuracy on Complex Tasks
On simple, well-defined decisions, Jev holds its own against strong LLMs. On harder tasks, it can fall behind.
In TypeSafe's workflow evals, Jev averaged 67.8% agreement across four business workflows, nearly matching GPT-5.6 Terra at 67.9%. On invoice processing, the most complex of the four, Jev scored 61.8% while top LLMs reached 75% to 79%.
Keep in mind what "accuracy" means here. TypeSafe measured how often each model agreed with the combined answers of two frontier models, GPT-6 Astra and Claude Fable 5.1. That's a useful benchmark, but it's different from accuracy against human-labeled data.
6. Reasoning and Explanation
Jev can't explain why it chose an answer, summarize a document, or fill in a free-text field. It gives you the decision and the probabilities behind it, and nothing more.
LLMs can walk through their reasoning, write a rationale, and handle follow-up questions. That makes them the better fit whenever a person needs to understand or review the "why."
When Should You Use Jev vs an LLM?
In short, use Jev when you can list every valid answer in advance and the same decision repeats at volume or needs to happen in real time. Use an LLM when the task needs language, reasoning, or answers you can't define ahead of time.
Jev is the better choice for these kinds of tasks:
- High-volume classification: Tag thousands of support tickets by team, score inbound leads against your ideal customer profile, or moderate user content.
- Real-time decisions: Make calls inside an app or UI where a response has to land in under half a second.
- Agent control flow: Choose the next tool, decide whether an agent should continue, retry, ask the user, or stop, and flag risky commands before they run.
- Guardrails and verification: Check LLM outputs, tool calls, and fetched pages for policy violations, prompt injection, or unsupported claims.
- Model routing: Decide which LLM should handle each prompt, and escalate only the hard ones to your most expensive model.
- Search and reranking: Score how relevant each document is to a query before passing the best context to an LLM.
An LLM is still the right tool for these tasks:
- Writing and summarizing: Draft emails, reports, replies, and summaries.
- Open-ended questions: Handle requests where the possible answers can't be listed ahead of time.
- Multi-step reasoning and planning: Break down a problem, research it, and decide what to do next.
- Low-volume work: Skip the setup when a task runs only a few times and speed or cost won't make a real difference.
- High-stakes extraction: Pull structured facts from messy documents like invoices, where top LLMs still outperform Jev.
How PromptQL Uses Both Jev and LLMs
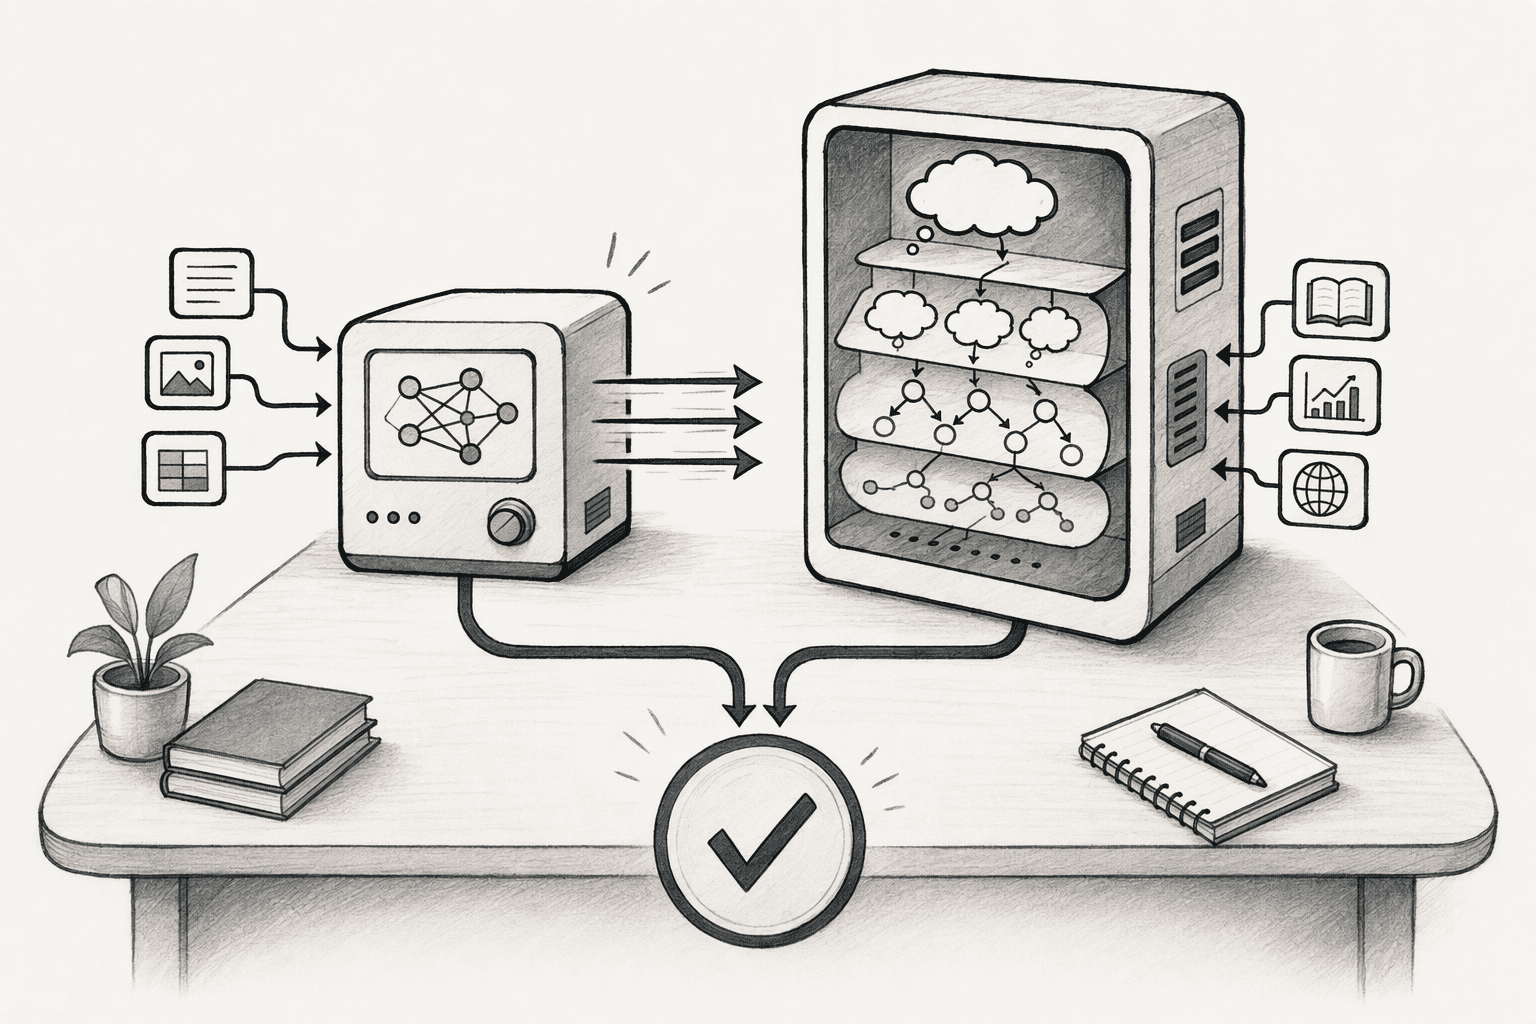
PromptQL puts both models to work in the same place, so you don't have to pick one for an entire project. Each step goes to the model that suits it best.
When you give a PromptQL bot a task, the LLM side handles the thinking. It plans the work, connects to your data sources, writes and runs code, and drafts the final output. When that work includes a large batch of repeated decisions, the bot can hand them to Jev in workspaces where the Jev integration is enabled.
Here's how that plays out in a job search workflow:
- The LLM builds the shortlist: It reads your background, asks about your preferences, and researches around 10 roles with reasons each one fits.
- Jev scales the evaluation: It scores 100 or more listings as strong, possible, or unlikely fits and flags low-confidence results for your review.
- The LLM drafts next steps: It prepares tailored application answers and outreach messages for the roles you pick.
Everything happens inside shared, multiplayer threads. So, your teammates can review the same results, and the bot only accesses the data each person is allowed to see. To learn more about how PromptQL keeps models swappable while your context stays in place, see its architecture overview.
Conclusion
The real shift Jev brings is in how you design AI workflows. Instead of picking one model per project, you can pick a model per decision.
Every step becomes a simple question. Does this call need language, or does it need a verdict? Send verdicts to Jev and language to an LLM, and your workflows get faster and cheaper without losing the reasoning where it counts.
If you want to see that split in action, you can try PromptQL or browse upcoming Jev workshops and events.
Frequently Asked Questions
Does Jev replace fine-tuned classifiers like BERT?
Sometimes. A BERT-style classifier needs labeled examples, training time, and ongoing maintenance, and how many examples depends on the task. Jev works from a few sentences of instructions with no training, so you can test a new classification idea in minutes. But independent tests are mixed, and a trained classifier with enough labeled data can beat Jev on accuracy. If you already have a well-tuned classifier that performs reliably, compare both on the same labeled examples before you switch.
Is Jev safe for automated decisions?
Jev can be safe for automated decisions if you add checks around it. Text inside the input can steer its answers. In one test reported by VentureBeat, a fake "pre-approved" note cut Jev's block probability for a destructive command from 0.76 to 0.48. Check Point Research also broke Jev with injected text in every attack setup it tried. Independent tests found that option order can shift results on some questions. To reduce the risk, pin a specific model version, pair Jev with rule-based checks and permission controls, log every decision with its confidence score, and keep a human review step for high-impact actions.
Can Jev process images?
Not directly. Jev's hosted model works with text and structured data such as JSON. If your data includes images, convert them to text first, such as a caption or transcript. TypeSafe's launch demos run on structured text, and the launch post marks image input as something that may come later.
Where can you access Jev?
You can access Jev through TypeSafe's HTTP API or its official Python and JavaScript SDKs. It's also available on Vercel AI Gateway, OpenRouter, Cloudflare, LangChain, and inside MotherDuck SQL through the prompt_jev() function. TypeSafe opened direct signups to everyone on September 20, 2026, then paused them two days later because of demand. Signup availability and free credits have changed several times since launch, so check TypeSafe's sign-in page for the current status. If you can't get an account, a gateway like Vercel AI Gateway gives you access through its own account.
Is Jev a type of LLM?
No, Jev is not an LLM. It gives up text generation entirely and uses a different architecture and training method, which TypeSafe calls Reinforcement Learning for Calibrated Decisions (RLCD). LLMs are usually trained with methods like reinforcement learning from human feedback (RLHF), which optimize for text that people prefer.
Who makes Jev, and is it open source?
TypeSafe AI makes Jev, and it is not open source. TypeSafe was founded by Diogo Almeida, a former OpenAI researcher who helped develop the training methods behind ChatGPT. Jev is a proprietary, hosted model that you access through TypeSafe's API, and its weights and architecture details have not been published.
Sources
- Case 1:26-cv-11549-IT Document 285 Filed 09/04/26 Page 1 of 49 UNITED STATES DISTRICT COURT DISTRICT OF MASSACHUSETTS * LEAGUE OF - ag.ny.gov
- 23-1217 - United States v. Milliron [11292334] | Tenth Circuit | The United States Court of Appeals - www.ca10.uscourts.gov