Most enterprises already run on repeated decisions: which team gets this ticket, whether a listing breaks a policy, whether an alert is worth an analyst's time, which model should handle a request. The hard part isn't deciding to use AI for them. It's choosing which decisions are worth handing over, and most lists of AI use cases are too generic to help with that.
Jev suits a specific slice of that work. TypeSafe AI built it to answer closed questions about text with a choice, a score, or a yes/no probability, at a speed and price that lets it run on every item instead of a sample. That points to a clear set of enterprise use cases, along with a few things to check before relying on it.
This guide covers what Jev is good at and the enterprise use cases that follow from it.
Key takeaways
- Best fits: Decisions that repeat at high volume, have a closed list of answers, and can be checked by a threshold, a rule, or a person.
- Evidence: Public results are early and mostly small, so any use case needs a test on your own data.
- Regulated data: Check TypeSafe's data terms and compliance evidence before sending regulated data.
- Batch and live: Some use cases run as batches over stored data, and others sit in the live request path.
What Jev is good at
Jev is narrow by design, and that narrowness is what makes it useful in an enterprise. Its strengths are specific:
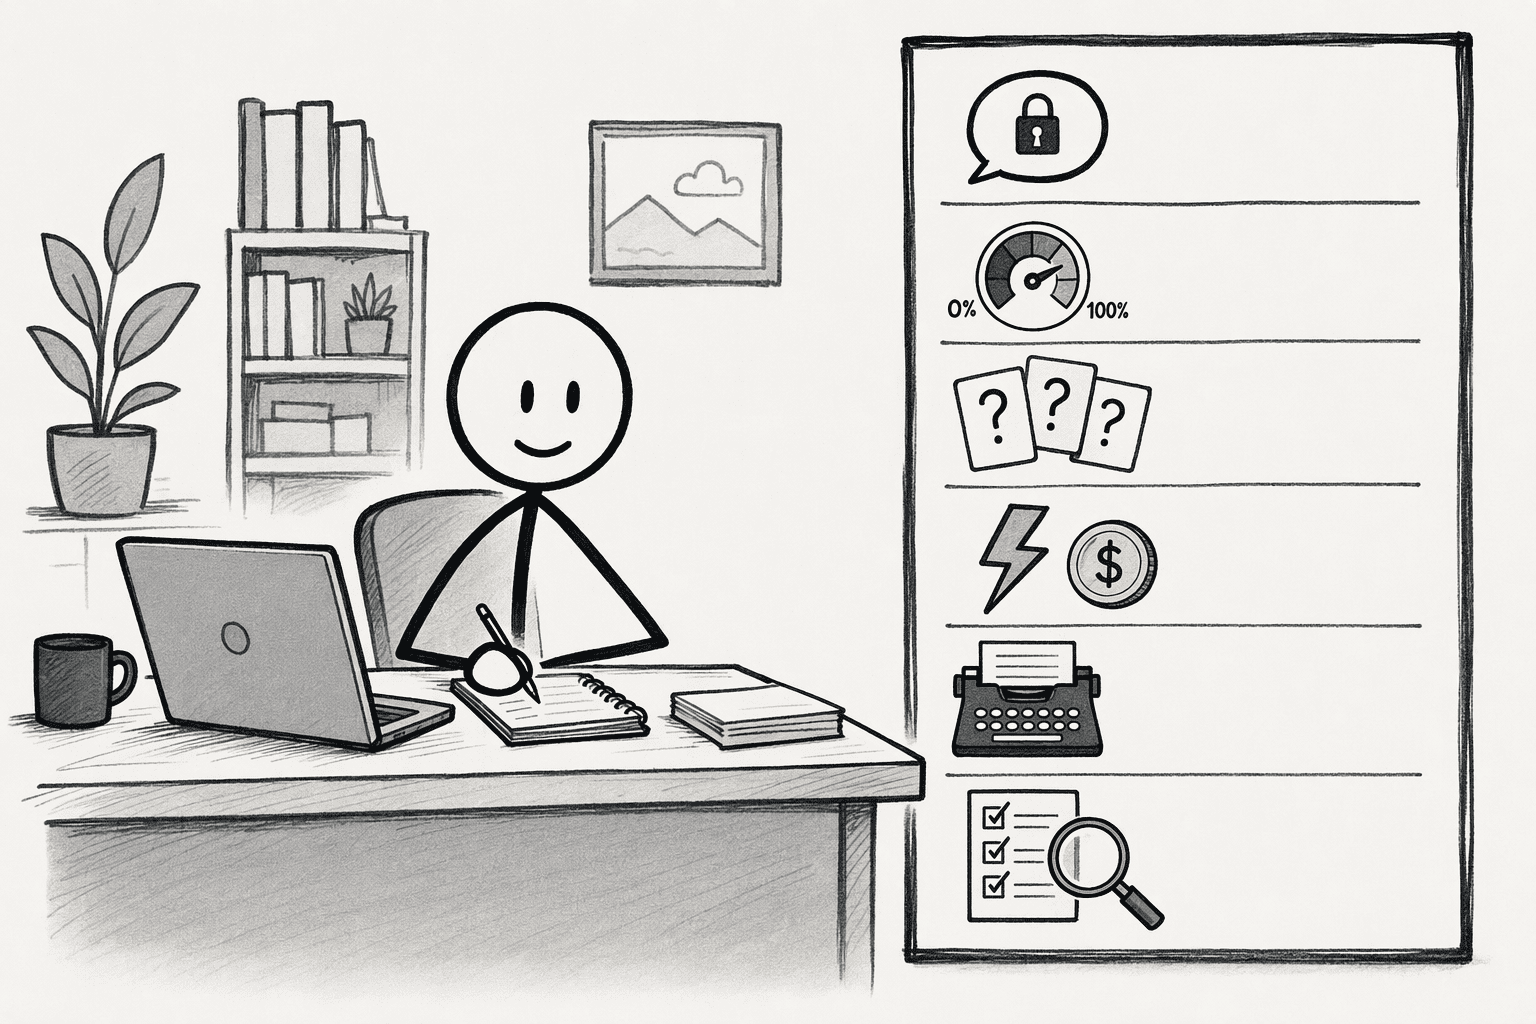
- Closed answers: It picks one option from a list of up to 255, rates an item on a scale of 2 to 10 described levels, or gives the probability of a yes/no statement, using three question types called Choice, Score, and Noul.
- A probability on every answer: TypeSafe's docs say Jev is trained to return calibrated decisions, which is a vendor claim to confirm on your own data, so uncertain items can go to a person.
- Several questions at once: One request can carry a set of questions about the same item, and adding more costs only marginally more.
- Speed and low cost per decision: TypeSafe reports response times of 70 to 500 milliseconds at an early-access price of $0.042 per million input tokens, with output free.
- Typed, consistent output: There is no free text to parse, and it can't return a label outside the list a team defines.
- Checking everything instead of a sample: Because each decision is fast and cheap, it can run on every item, which is what makes the use cases below practical.
The best enterprise use cases for Jev
Using these strengths, enterprises are applying Jev to decisions that repeat at volume. Seven stand out. Some run as batches over stored data, while others sit in the live request path.
1. Support and email triage and routing
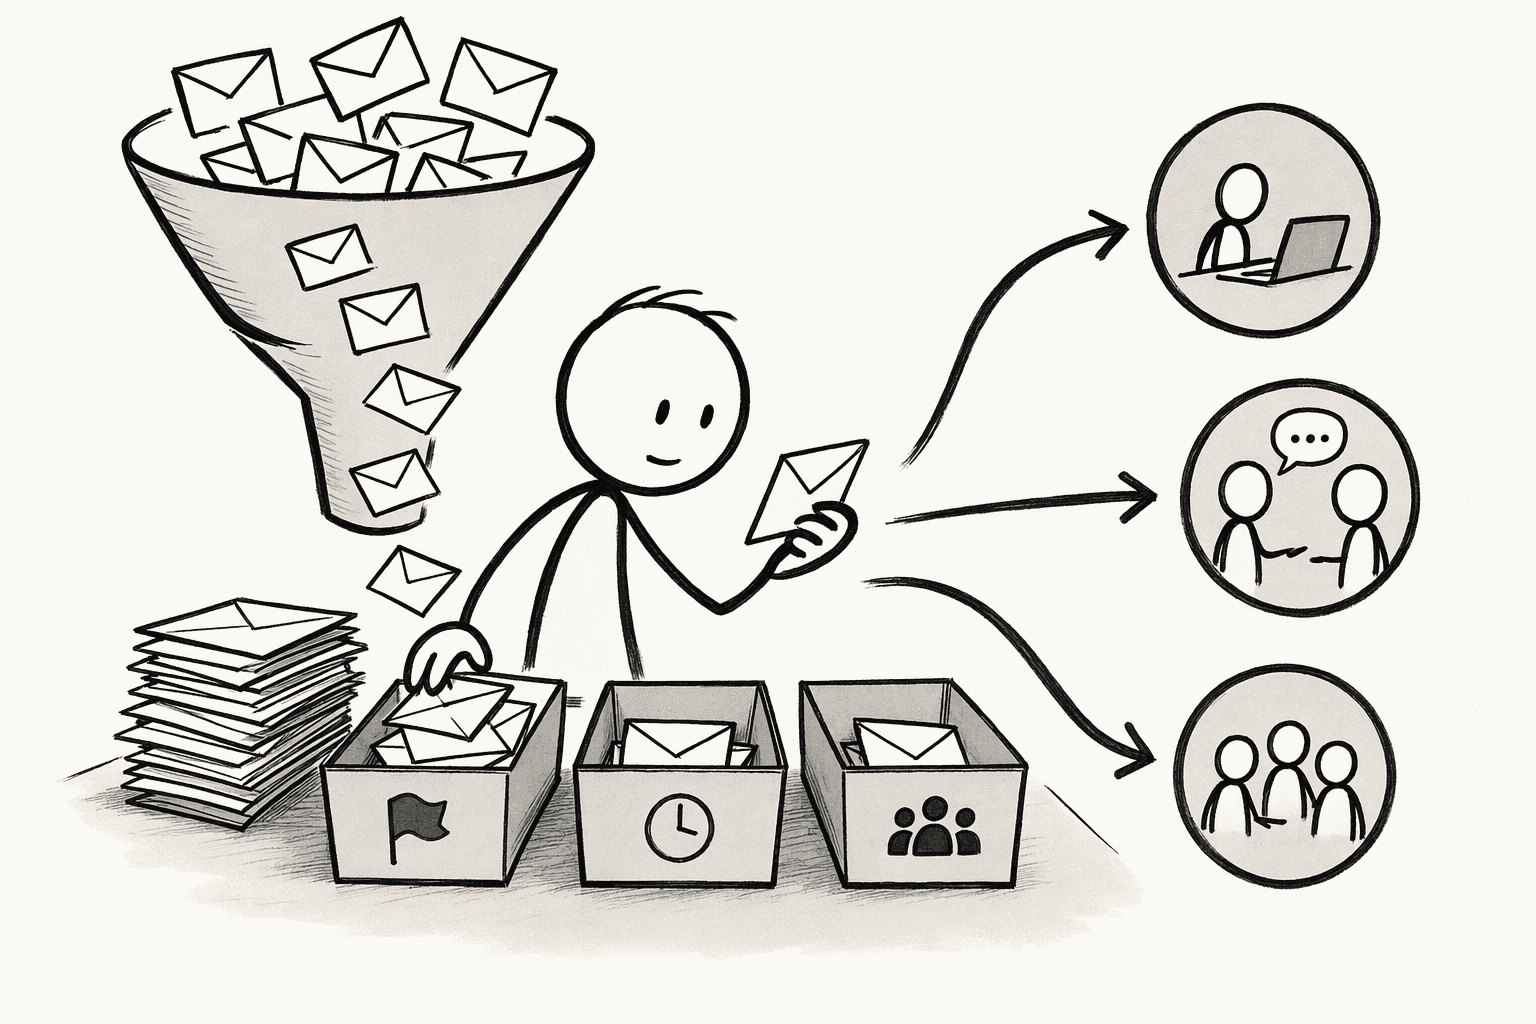
Jev picks the team a ticket belongs to, flags urgency, and rates frustration in one request, so each message arrives in the right queue with a priority signal. It fits because the labels are a short, known list and thousands of messages arrive daily. Low-confidence tickets go to a person, and known facts such as account tier stay as rules in code, a pattern covered in Jev vs ChatGPT.
2. Content and listing moderation
A yes/no question per policy plus a severity score lets Jev flag spam, abuse, or rule-breaking listings in milliseconds. It fits because moderation is high volume, latency-sensitive, and built on written policies. Content above a threshold is removed and borderline items go to a review queue.
NearHere's own tests found Jev scoring at or near a small LLM on event-listing checks at a fraction of the cost per decision, on small samples.
3. Risk screening for fraud, claims, KYC, and security alerts
Jev answers a set of closed questions about a claim, transaction narrative, document, or alert, such as what the disposition should be, how severe it is, and whether it looks like a false positive, then routes the item by the answers. It fits because these queues are high volume and mostly routine, with the hard cases already going to analysts.
Public evidence here is mostly analyst write-ups and community builds so far, and regulated data needs a compliance check first, since one analysis found no SOC 2 or HIPAA attestations in TypeSafe's public docs at launch, although a data processing agreement and zero retention for enterprise customers are offered.
4. Model routing and cost control
Jev scores how hard each request is, and code sends it to the cheapest model that can handle it. It fits because the routing call has to be quick and cheap compared with the calls it steers, and LiteLLM's Auto Router lists Jev as a classifier option. Requests Jev is unsure about fall back to a stronger model.
5. Agent guardrails and action gating
Before an agent runs a proposed action, Jev can answer a yes/no question such as whether it looks destructive or out of scope, and the action proceeds, waits, or goes to a person.
It fits because the check is fast enough to sit in every step of an agent loop. Text inside the input can steer Jev's answer, so hard rules and permissions stay in place alongside it, as Jev and an LLM in one workflow lays out.
6. Evals and LLM-judge replacement
Jev runs the same checks an LLM judge would, such as whether an answer is relevant, safe, or on policy, as typed answers on every output instead of a sample.
It fits because evaluation is a closed question repeated at volume, and LangChain's judging test found Jev far cheaper and faster than LLM judges, with the saving depending on which judge it replaces.
7. Bulk labeling and enrichment
Jev tags, categorizes, or screens very large sets of records, such as support tickets, product feedback, articles, or documents, with a label and a probability on each.
It fits because the work is a closed question over every row, and in MotherDuck's test Jev classified 100,000 news articles in 40 seconds for $0.50 at 89% accuracy, against 88% for a comparable LLM at $37.58, though MotherDuck is an integration partner. Low-confidence rows are reviewed by a person.
Where PromptQL fits with Jev in the enterprise
Everything above is a decision step inside a larger workflow, and PromptQL fits around it. Decisions made in the request path, such as moderation or guardrails, are called from the application or from Zapier, Make, or n8n, which all have official Jev integrations. Where it fits is the batch work that surrounds those decisions, across the data a company already has:
- Batch decisions over connected data: PromptQL connects to warehouses, databases, and SaaS apps, and in workspaces where Jev has been provisioned, a plain-English request hands a task's repeated decisions to Jev, such as sorting a ticket backlog or labeling a large set, as laid out in using Jev without writing code.
- Labels joined to business data: Jev's labels can be joined to account, revenue, or plan data from other systems, so results can be weighed by who they affect.
- Review in a shared thread: Low-confidence items come first, and teammates can be invited in to correct the criteria, then the setup is reused for the next batch or turned into a dashboard.
- Access and records: Permissions are enforced at the data layer using the access of the person asking, and every action is logged.
Conclusion
The best use cases for a decision model share a pattern: a short, known list of answers, a high volume of items, and a backstop for the answers that aren't certain. Support triage, moderation, routing, guardrails, evaluation, and bulk labeling all fit it, and risk screening fits it with extra care for regulated data. Because public evidence is still early, the way to choose is the same for every candidate: test it on your own cases and let the results decide.
Frequently Asked Questions
What is the best first use case for Jev?
One with high volume, a short list of known answers, and an easy backstop, such as support triage, moderation, or bulk labeling. The cost of a wrong answer is low, and a person can review the uncertain ones.
Can Jev handle regulated data?
Check first. TypeSafe offers a data processing agreement, says it doesn't train on customer data, and offers zero retention to enterprise customers, but one analysis found no SOC 2 or HIPAA attestations in its public docs at launch. Ask TypeSafe directly and redact personal data before sending anything.
Does Jev replace an LLM?
No. Jev returns choices, scores, and probabilities, not text, so writing, summarizing, coding, and explaining stay with an LLM. Most enterprises use both, with Jev handling the repeated decisions.
How do you pick a use case?
Apply a simple fit test: a closed list of answers, text input, volume or speed pressure, a wrong answer someone can catch, and no explanation required. Then run a few hundred labeled cases through Jev and compare the results with the current process before moving any traffic.